Summary
When delegating the same work to Codex repeatedly, specify both the tools it should use and how to review the result.
- Nine usage scenarios and ten checks to run after implementation were added to a GitLab issue. The model stayed the same. The skill’s writing rules, examples, and review process changed.
- When querying the same CloudStack deployments, the run that explicitly used an API-only skill finished its report without opening a browser.
- When comparing outcomes, check whether the first result was usable and how long corrections and review took.

Examples of skills and tools in use
I examined two questions about recurring work.
- Does documenting in a skill how to read and write a feature request help include more of the conditions an implementer needs?
- Does defining the tools and what they are allowed to do help an agent produce the required result using the requested route?
What tools and skills do
The GitLab API is a tool for finding issues, creating them, and reading back saved content. A skill explains when to look for existing issues, what a feature request should contain, and what to compare after posting. Put the procedure in SKILL.md and include templates or scripts when needed. OpenAI skills documentation
| Component | Example for writing a GitLab issue |
|---|---|
| Tool | List issues, create or edit an issue body, read back what was saved |
| Skill | Search for duplicates, read related code, describe expected behavior for each action, compare the published issue with the draft |
| Individual request | Target project, feature to change, and whether to draft or create the issue |
A script can read back the saved issue by number or check whether an attachment link opens. Codex interprets the request and identifies anything inconsistent with the existing code. The skill specifies what each step reads and what it passes to the next step.
Comparing two versions of a GitLab issue
The request was to let users mark a project or group inactive before deletion and permit that transition only after every deployed service had stopped. I used the same model and reasoning setting for the initial and revised issue bodies. Both versions used a skill for posting issues.
| Information in the issue body | Initial version | Revised version |
|---|---|---|
| Request and scope | Request summary and four conditions | Conditions for projects and groups, existing behavior, and what changes |
| User actions | No usage scenarios | Nine scenarios linking situations, actions, and expected behavior |
| Checks after implementation | No checks | Ten checks to run after implementation |
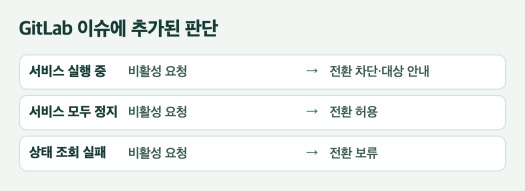
The revised issue gave developers concrete behavior to implement.
- Block deactivation if the group contains any running deployment. Identify the projects and services still running.
- Describe what happens when there is no deployment, when a service fails to stop, or when its running state cannot be read.
- When marking an existing project active, change only the project’s administrative status. Leave deployed services in their current running state.
The initial skill described how to search for issues and post through the API. For the revision, I expanded the rules for feature requests and also incorporated examples the user selected, project code, and a separate draft review. To isolate the effect of the skill instructions, keep the material and review process fixed and vary only the skill version.
How we queried CloudStack deployments
We looked up deployments and IP addresses for the same project in our internal CloudStack system from two environments.
- The first run found one project, five deployments marked as running, and four allocated IP addresses that matched the configuration through the API in a few minutes. It then opened the admin interface. The user instructed it to use only the API, and the run stopped.
- The run on another Mac explicitly used the CloudStack skill. It read the same deployments and IP addresses through the API, put them in a table, and identified deployments without an IP address.
The observed difference was whether the run reached the final report using the requested API route. The first run’s API query also took only a few minutes. The environment, browser investigation, and stop affected total work time. To compare time, repeat the lookup in the same environment and measure from the request through review.
Deployment status in the management API does not show whether a website is reachable or whether the application can make its internal connections. In a separate investigation, Codex used the management API to check deployments and IP addresses, then used read-only SSH authorized by the user to check a database connection. For GitLab, the API handled issue creation and the browser was used to issue a token at the user’s separate request. Documenting which route to use for each purpose and what it can show can reduce unnecessary queries.
Designing tools for recurring work
- Find tasks that recur. Look for records of the same queries, comparisons, or operations happening more than once.
- Start with tasks that often need manual work. Consider how often the task occurs, how long it takes, what people have to check, and what must be repeated if it fails.
- Describe the input and result in one sentence. For example, take a project name and return deployment statuses and allocated IP addresses.

| Task | What the tool does | What to review |
|---|---|---|
| Inspect project status | Read the project, deployments, and allocated IP addresses | Status by deployment, matching IP addresses, and unset fields |
| Restart a service | Restart the specified deployment, then read its status again | Whether the request was accepted, the subsequent status, and what connectivity was tested |
| Create a GitLab issue | Search, create, and read back the issue | Issue number, saved body, and whether attachments open |
| Check a course exercise | Run notebook cells and compare their output | Failing cells and expected and actual values |
Read and write operations can share the same API client code. Define separate operations for the actions they perform.
- A lookup takes a project name or ID. A restart requires the exact deployment ID and permission to make changes.
- Report duplicate names, missing targets, insufficient permissions, or incomplete results as part of the output.
- If the connection drops after you submit a change, read the target again. Check whether the change already took effect before deciding to retry.
Build a tool that accepts a project name and reads deployments and allocated IP addresses. If more than one project has the same name, return the matches. Show a missing address as unset. Test a successful lookup, a duplicate name, and insufficient permissions separately.
What to document in a skill
If the same correction comes up repeatedly, add the instructions you had to repeat to the skill.
- For GitLab issues, describe when a feature permits or blocks an action and what the user sees.
- When making course material, review earlier exercises and solutions, run the new solution code, and compare the output with what you expect.
- For video production, document starting the generation job separately from retrieving and delivering the finished video.
Describe when the skill applies, what to read, which changes are allowed, and how to check whether the task is complete. In a new conversation, try a straightforward request, one with an ambiguous target, and a read-only request.
Codex can load a skill when the request names it directly or matches its description. In the CLI and IDE extension, specify it as $skill-name. To make automatic selection possible, describe the tasks and scope in the skill description. We set the internal CloudStack skill to allow_implicit_invocation: false so it loads only when named explicitly. OpenAI documentation on invoking skills
Comparing outcomes across users
For recurring team tasks, put shared procedures in a team skill. Add procedures for individual work separately. To share tools, also align the execution environment and account permissions.
To assess differences among users, hold the model and work materials fixed and compare runs with no skill, with a shared team skill, and with an individual skill.
- Was the first result usable? Record the share of runs whose results were used without another edit.
- How many follow-up instructions were needed? Count the instructions people sent to fill gaps or correct behavior.
- How long did the work take? Measure from the initial request through review and rework.
The GitLab revision explained what to implement in more detail. The CloudStack run reached its report using the requested API route. Assessing differences in user productivity requires repeated runs by several people under the same conditions.
Series overview · How the Way You Use Codex Affects the Outcome
“Designing Codex Skills and Tools for Everyday Work”에 대한 한개의 댓글