Summary
Even with the same model, the outcome can vary depending on what you delegate to an agent and how you check the result. Codex work records show how skills, instructions sent during a run, and completion checks affected the results.
- A skill specifies which tools to use and what to check before ending the task.
- Use Steer to adjust the work in progress. Put tasks that should follow it in the Queue.
- A completion check means opening a file to make sure it was saved and trying the action the user needs to perform.
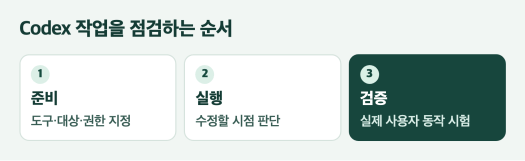
Tools and steps for recurring tasks
I wrote the same GitLab issue twice with the same model and reasoning setting. The first version summarized the request and listed four conditions. For the second version, I reviewed example issues and the related code, then documented in the skill when the feature should permit or block an operation. I also added a step to read back what GitLab saved.
- The first version of the issue described the feature to change and when the change should apply.
- The revised issue described nine situations a user could encounter and ten checks to run after implementation.
For example, the revised issue says to block deactivation while services are still running in the group and identify the project and services that remain active. The second version combined a change to the skill with example issues, code research, and draft review. To learn whether the skill alone produces the same difference, the inputs and review process would need to stay the same.
The GitLab API creates an issue and reads back the saved content. The skill describes which issues and code to examine, which conditions to include in the body, and what to check after posting. In our internal CloudStack system, listing deployments and restarting a service also require different inputs and permissions. Defining these operations individually makes it clear which tool belongs with each task. OpenAI skills documentation

Changes during a run and follow-up work
Just before a cost analysis went live on WordPress, I asked Codex to change the download link text. Codex returned to the editor, updated the text, and published the post in the same run. I discovered a mistake in the cost comparison units after publication. A new run corrected the table and conclusion and updated the published post.
- Use Steer to apply a new requirement to the work in progress. Changing link text before a post goes live is one example.
- The Queue holds requests that should start when the current task ends. When I requested a separate Q&A board while an attendance rate was being corrected, the board request stayed in the queue.
Updating link text and recalculating costs take different amounts of work. These records let us compare when each change was applied. Measuring how much time one approach saves would require sending the same correction for the same task and changing only how it was delivered. Cost analysis post · OpenAI’s explanation of Steer and Queue
What users need to do and how to check it
- In OneDrive, 18 items were still pending after a test file had reached the server. After saving nine local files and reconnecting the shared folder, the pending count dropped to zero. I then tested both upload and download.
- In the diagram library, administrators could sign in and download original files. Regular users still had a sign-in error, so I corrected their permissions. I then tested viewing as a regular user and editing as an administrator separately.
A successful test upload or administrator sign-in tells us whether that specific action works. A task is complete when the person who requested it can perform the actions they need.

How requests change after seeing a first result
Selecting diagrams from slide decks and organizing them in Excel and HTML led to building a library for the team. After opening the list, we added search and original downloads for team members and uploads for administrators. On a project that integrated external organizations’ materials, inspecting the existing admin screens revealed a way to change fewer files. Seeing the first result helps specify the users and actions the next request should cover.
How to compare outcomes
Keep the model and permissions the same and repeat similar work to compare ways of using Codex. Have several people work with and without skills and vary how they send instructions. Record the following.
- Did the first result meet the requested behavior and format?
- How often did a person intervene, and for how long?
- What was the total completion time, from the request through review and rework?
A study of 5,172 customer support agents found that AI assistance increased issues resolved per hour by an average of 15%, with larger gains among less experienced staff. The figure comes from customer support. A comparison like the one above could test whether shared skills also reduce differences among Codex users. Generative AI at Work
“How the Way You Use Codex Affects the Outcome”에 대한 한개의 댓글