Summary
What people first delegate to AI depends on how they expect to use the result. Trying an initial result can change what they delegate next. I compared how the requests changed for a diagram library and for an integration with external organizations.
- The diagram library started as a ranked list. After opening the list, the user asked for a service with search, uploads, and downloads.
- For the external data integration, reviewing the existing admin screens led to a proposal that changed fewer files.
- When deciding what to request next, run a small trial with real material and establish what worked.
From a ranked list to an internal library
The first request was to find, evaluate, and rank system architecture diagrams in existing presentations. Codex examined 2,331 PowerPoint files and evaluated 1,389 diagrams. It produced the rankings in Excel and displayed the images in HTML. The HTML page supported search, sorting, and zoom, and showed where each diagram appeared in its source slides.
- The initial action was to open the evaluated diagrams and compare them.
- The next actions were for team members to search and download the originals and for administrators to upload new material.
Moving from a list to a team library meant adding sign-in, uploads, and downloads. The deployment API could not accept the files, so we built from source on the server. We added 1,389 diagrams and 1,014 source presentations and tested administrator sign-in and downloads. We checked regular-user permissions separately.
The cost analysis followed a similar path. The account data became a report and a WordPress post. Correcting the comparison units after publication helped define a procedure for future posts. I documented how to save a draft, attach a file, and read back the result in a skill. Published cost analysis
Reducing implementation work by reusing existing features
For the external data integration, we initially considered scripts for every step from collection to transfer. Reviewing the admin screens and code together showed that the interface could already handle some of the steps.
- The existing screens supported organization registration and approval, collection scheduling, field mapping, collection requests, and transfer.
- The work still needed was transformation code for each organization, deployment, and search index creation.
The investigation led to a proposal that reduced the number of files requiring changes from 39 to 11. The 11 files were part of the narrower proposal. Applying it and rerunning the process from collection through search were still pending.

Using the first result revealed more features the library needed. Reviewing existing features showed that the integration needed less new development. The conversations show how the requests and deliverables changed. They do not record which possibilities the user had considered at the beginning.
Defining the goal and exploring ways to reach it
The OneDrive recovery request did not specify where to find the files or how to save them. Codex noticed that items were still pending even though a new file uploaded, so it investigated the shared folder. It separately saved nine files Finder did not show and reconnected the folder. It then checked that the pending count fell from 18 to zero and tested uploading and downloading. When a user sets a clear goal, an agent can adapt its investigation as it learns more.
Another case showed why it helps to be clear about the scope. I asked whether the existing installation script would still work if the Git repositories were updated separately on each server. Codex edited the script before answering. After I restated the question, it confirmed the existing script would work if the paths matched. For a research task, it helps to say which approaches to compare and when changes can begin.

Testing what to delegate with real material
A study by Bansal and colleagues examined how people make decisions after seeing AI predictions. Knowing where the AI was likely to make mistakes could affect how well people and AI worked together. In a separate experiment with consultants using GPT-4, the group using AI was on average 19 percentage points less likely to produce a correct answer on a task the model found difficult. The two studies differ from a Codex delegation experiment. The differences make it useful to test the work you actually plan to delegate. Beyond Accuracy · Navigating the Jagged Technological Frontier
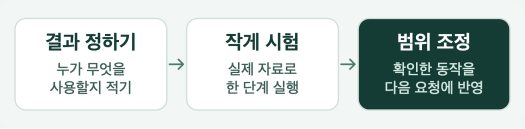
- Specify who needs to do what. For a diagram library, decide whether team members need to search for diagrams and download the source slides next month.
- See which tools are available. Identify what the agent can read or change in the interface, API, and repository.
- Run a trial with a few real items. Test search and download with a few presentations, or run one organization’s integration workflow in the development interface.
- Use the trial to shape the next request. Save steps you can repeat in a skill and decide whether a step that failed needs a different tool or a person.
Team members need to be able to search for the same material and download the originals next month. Investigate what the available tools and permissions allow, and compare the work needed to reuse the current system with the work needed to build a new one. First propose a trial with one item. Change original files and production settings after we choose an approach.
To test whether initial expectations affect outcomes, give several users the same model and tools, show only some of them the results of a real trial, and compare the scope and completion rates of their follow-up requests.
Series overview · How the Way You Use Codex Affects the Outcome
“Deciding What Work to Delegate to AI”에 대한 한개의 댓글